Overview
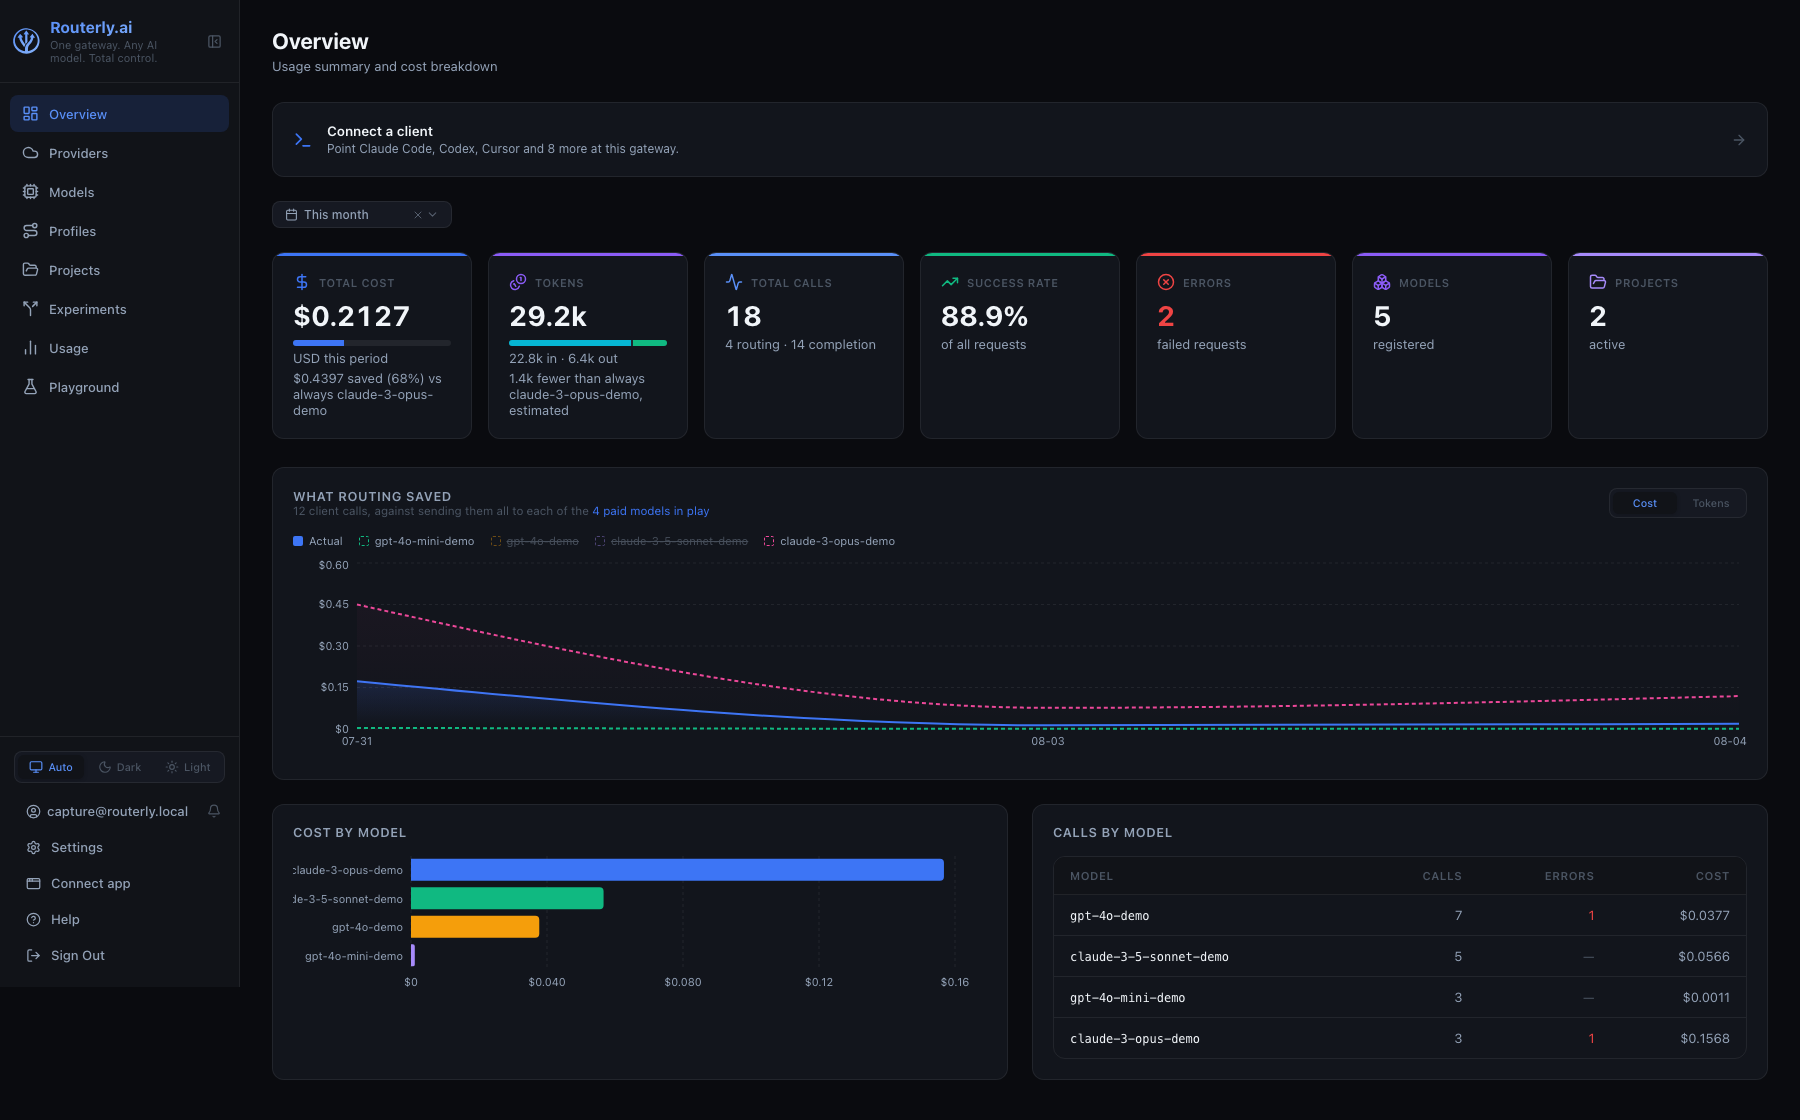
The Overview page is the dashboard home screen. It shows a snapshot of activity across all routers for the selected time period.
Period Selector
A date range picker at the top of the page selects the reporting window: the same one the Usage page carries, with the same presets (today, yesterday, last 7 days, this month, and so on), a custom from/to range, and All time.
The entire page — cards, charts, and tables — updates instantly when you change the window. The savings chart follows it too: a window of two days or less is bucketed by hour, anything longer by day.
Summary Cards
The top row shows aggregate numbers for the selected period:
| Card | Description | Links to |
|---|---|---|
| Total Cost | Sum of all LLM costs in USD, with what routing saved against sending the same traffic to one model every time as a second line | Usage |
| Total Calls | Number of API requests, with a routing vs. completion breakdown in the sub-text | Usage |
| Success Rate | Percentage of requests that returned a successful response | Usage |
| Errors | Number of failed requests (provider errors, budget exceeded, and so on) | Usage |
| Models | Number of registered models | Models |
| Routers | Number of routers | Routers |
| Time saved | The same comparison in wall time over the whole period | — |
| Tokens saved | What the optimizers really removed, plus the tokenizer estimate as a second line | — |
Every card except the two saving ones is a link to the section that explains its number, so a figure that looks wrong is one click from the records behind it. The saving cards are explained by the card below them.
A saving is shown only when it is positive. Money saved rides on Total Cost, the number it changes, and disappears when routing came out level or more expensive; the same holds for the Time saved and Tokens saved cards. A window too small to compare produces no saving line at all rather than a zero or a red number.
Token Strip
Below the summary cards, a strip shows aggregate token counts for the period:
| Metric | Description |
|---|---|
| Input tokens | Total prompt tokens sent to providers |
| Output tokens | Total completion tokens received |
| Cached tokens | Tokens served from the provider's prompt cache (counted at the reduced cached rate) |
What Routing Saved
A single card compares the traffic that actually happened with the same traffic sent to one model at a time. The header says how many client calls were compared, over how many baseline models, and links to Models.
Which models it compares against
A baseline is a single-model policy the operator could really have run instead of routing, so the comparison only covers the paid models in play in the selected period:
- every enabled target model of the routers that produced traffic in the period,
- plus every model that actually served a client call in it.
Free models are left out because they make the cost comparison meaningless, and embedding models are left out because they cannot answer a completion call. A model that only served the gateway's own routing or guardrail calls is not a baseline either.
The saving cards
The saving figures in the top row read this comparison. Each one is anchored on the costliest model in play, the worst case routing avoided, and names it: vs always claude-opus-4-6.
| Figure | Description |
|---|---|
| Total Cost, second line | What routing saved against always using the anchor model |
| Time saved | The same comparison in wall time over the whole period, from each model's own throughput in it. Models that never answered in the period carry no estimate, so this card falls back to the costliest one that did |
| Tokens saved | Two different figures, kept apart: what the optimizers really removed, which is measured, and what a different tokenizer would have counted, which is an estimate |
The chart
A segmented control switches what the chart plots:
| Metric | Solid line | Dashed lines |
|---|---|---|
| Cost | USD actually spent per bucket | One line per model in play: the same calls priced there |
| Tokens | Input tokens per bucket | Output tokens per bucket (both solid: tokens have no counterfactual) |
| Speed | Measured milliseconds per call | Estimated milliseconds per call on the costliest model |
The dashed lines are counterfactuals: something that did not happen. Buckets with no comparable call are left out rather than drawn as zero, so a gap in the line means there was no traffic.
With more than a handful of models in play the chart would be unreadable, so it starts with only the two ends visible: the cheapest model and the costliest. Click any legend entry to show or hide its line, including the actual spend. Hidden entries stay in the legend, struck through. Changing the period recomputes which models are in play, and the two ends of the new set become the visible ones again.
Only client calls count. Routing and guardrail calls are the gateway's own overhead and are excluded, as are calls that carry no tokens. The same numbers are available from routerly report savings --trend and from GET /api/usage?series=1 (API: Savings series).
The cost figures are exact arithmetic on the observed token counts, but a different model tokenizes the same text slightly differently and may answer at a different length. The token range is derived from a ratio per tokenizer family, not by re-tokenizing the prompts: Routerly does not retain them. Read the baseline as "the same conversation, priced elsewhere". Measuring the real difference needs a live comparison, which is what Experiments are for.
Cost by Model Chart
A horizontal bar chart ranks the top eight models by cost for the period. Models with no cost in the period are left out. Hovering a bar shows the full model ID and its cost.
Calls by Model Table
A table below the chart breaks down activity per model for the selected period:
| Column | Description |
|---|---|
| Model | Model ID as registered in Routerly |
| Calls | Total requests routed to this model |
| Errors | Number of failed requests for this model |
| Cost | Total cost in USD |
Rows are sorted by call count descending.
Navigating to Details
- Click any summary card to open the section that explains it: Usage, Models or Routers.
- The paid-model count in What Routing Saved links to Models, where prices and targets are configured.
- Use the Usage item in the sidebar for the full analytics page with filtering and drill-down by router, model, or date range.
- Click a router name in the sidebar to go directly to that router's configuration.