Dashboard: Usage
The Usage page provides aggregate analytics, per-model performance breakdown, and per-request logs across all routers. Use it to understand spending patterns, investigate errors, and drill into individual request traces.
Summary Statistics
The top row shows aggregated totals for the selected filter set:
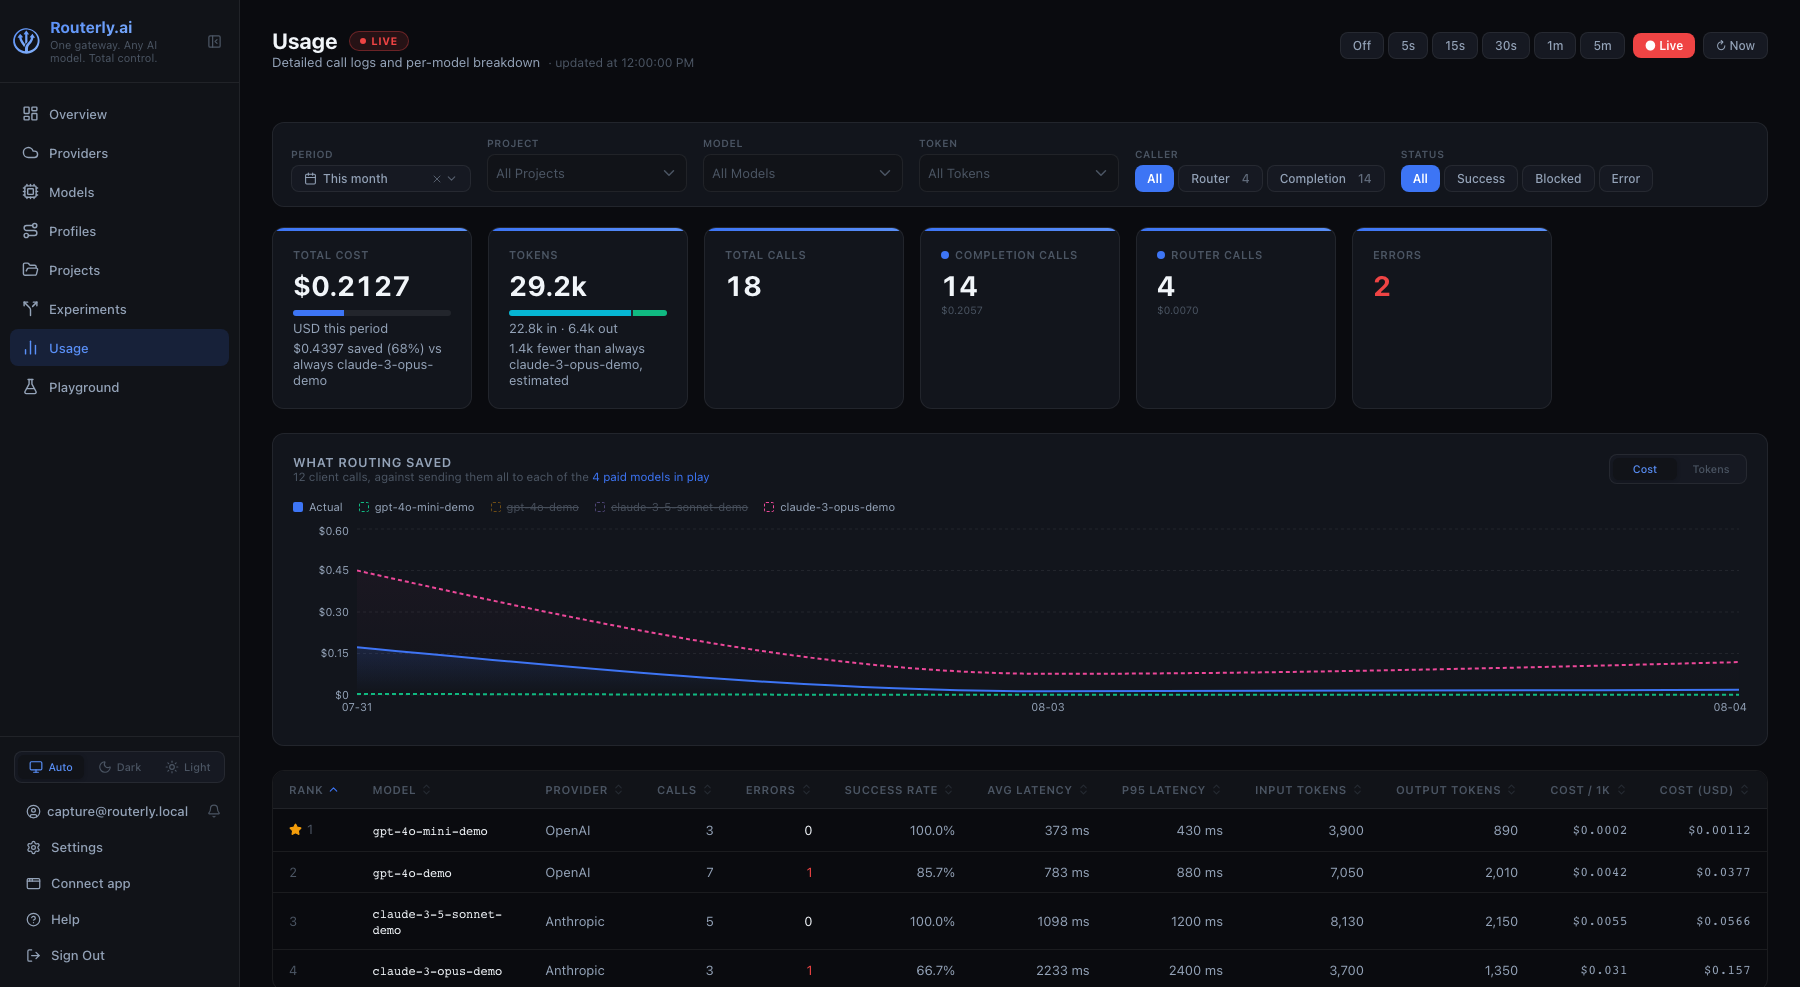
| Card | Description |
|---|---|
| Total Cost | USD cost of all successful calls in the period. When routing came out ahead, a bar draws the counterfactual bill to scale: the coloured part is what was paid, the gap is what routing saved, and the caption names the model it is compared against. A saving of zero or less gets no bar. |
| Tokens | Tokens in and out for the period, in compact form (1.2k, 4.3M), split to scale by a bar. The caption breaks it into in, out and, when the provider served any, cached. When optimizers cut tokens, their measured total is the second line; otherwise it is the estimated difference against always using the comparison model. |
| Total Calls | All usage records (completion + routing + guardrail + blocked) |
| Completion Calls | Main model inference calls, with their total cost |
| Router Calls | Model calls the router makes to decide where to route: the llm policy's decision call and the semantic-intent policy's embedding call, with their cost |
| Guardrail Calls | Model calls made by security rules (semantic, topic, moderation), with cost |
| Blocked Calls | Requests blocked by a guardrail rule before reaching any model. Shown only when at least one blocked call exists in the period. |
| Errors | Failed model calls -- blocked calls are counted separately and excluded from this number |
The Completion Calls and Router Calls cards double as filters: clicking one sets the Caller filter to that kind and outlines the card, clicking it again clears the filter.
Guardrail judge calls are charged to the router like any other model call and are subject to the router's budget limits. Blocked requests record zero cost and zero tokens.
What routing saved is read on the two cards that carry the numbers it changed: money on Total Cost, tokens on Tokens. There is no separate saving card, and no time-saved figure.
What Routing Saved
Below the summary cards, the same chart the Overview carries, over the filtered records rather than the whole instance: what the traffic cost, moved and took, against what the same calls would have cost, moved and taken on each single model that could have served them. The metric selector switches between Cost, Tokens and Speed, and the legend toggles each model line.
It follows every filter on the page but does not follow the live refresh: the comparison is expensive, so it is recomputed when the window or the filters change, not every two seconds.
Filters
| Filter | Description |
|---|---|
| Period | Preset time window (today, this month, etc.) or custom range |
| Router | Filter to a specific router |
| Model | Filter to specific model IDs |
| Token | Filter to the traffic that came in on specific router tokens |
| Caller | Who made the call: the client (Completion), the router, the guardrail pipeline, or an experiment judge |
| Type | What the call asked for, taken from the endpoint the client hit: Chat, Text Completion, Embedding, Rerank, Image, Audio |
| Status | All, Success, Blocked, or Error -- Blocked shows only guardrail-blocked requests |
| Session ID | Filter to requests from a specific session (from the x-routerly-conversation-id header). Lists the requests of one session; routerly report sessions lists the sessions themselves |
| End user | Filter to requests of one end-user ID |
| Tag | Filter by one tag as key=value (e.g., environment=production); same syntax as routerly report usage --tag |
Token lists every token of the selected routers, or of all routers when no router is picked, and appears only when there is more than one to choose from. A token is named by its first label, and by the visible head of the secret when it has none. Records written before 0.4.0 carry no token and drop out of the result as soon as the filter is set.
Caller and Type only offer the values the selected window actually contains, each with its call count next to it, and disappear entirely when there is nothing to choose: an instance serving only chat completions gets neither group. The counts are taken before those two filters are applied, so picking a value never changes the list you picked it from.
Filters are applied immediately and affect the summary cards, the savings block, the per-model breakdown table, and the request log simultaneously.
Every filter, including the period, is kept in the browser: a refresh, or coming back to the page later, restores the view you were looking at rather than the defaults. Use Reset to go back to the defaults.
The date range picker offers no future date: days after today are dimmed and not clickable, and the calendar stops at the current month.
Use the Session ID filter to view all requests from a specific conversation or user session. Use the Tags filter to analyze traffic by team, environment, application, or any custom dimension you tag your tokens with.
Per-Model Breakdown
Below the summary cards, a table ranks all models that received traffic in the selected period.
| Column | Description |
|---|---|
| Rank | Position in the cost-performance ranking; a model with no ranking data shows a dash and always sorts last |
| Model | Provider model identifier |
| Provider | Provider name |
| Calls | Total requests in the period |
| Errors | Failed calls |
| Success Rate | Percentage of successful completions |
| Avg Latency | Mean response time |
| P95 Latency | 95th-percentile response time |
| Input Tokens | Total input tokens consumed |
| Output Tokens | Total output tokens produced |
| Cost / 1K | Average cost per 1,000 tokens |
| Cost (USD) | Total spend for this model in the period |
A star marks the model with the best cost-performance ratio based on your own traffic. Every column header sorts. The table respects all active filters.
Past ten models the table shows only the head of the current sort, with a Show N more models control below it that expands the rest and folds them back. Sorting a collapsed table changes which ten are on screen.
The standalone Leaderboard page has been merged into this page. /dashboard/leaderboard redirects to /dashboard/usage.
Usage Table
Recent Calls lists individual requests, newest first. The heading counts how many records the active filters kept out of the period's total.
| Column | Description |
|---|---|
| Time | When the request arrived |
| Router | The router the request belonged to, with the token the call came in on underneath it |
| Model | Provider model used |
| Type | What the call asked for: Chat, Text Completion, Embedding, Rerank, Image, Audio |
| Caller | Who made the call: completion (the client), router, guardrail, or judge |
| In / Out | Input and output token counts |
| Cost | Estimated cost in USD, to three significant digits; anything below a millionth of a dollar shows as <$0.000001 |
| Latency | Total response time |
| TTFT | Time to first token, for streamed responses |
| Tok/s | Output tokens per second |
| Status | Outcome |
Every numeric column is right-aligned and uses tabular figures, so the digits line up down the column.
A call Routerly made on its own behalf (router, guardrail, judge) is
marked twice: its Caller cell is a coloured badge, and the whole row carries a
matching coloured bar on the left edge. Client completions, which are the bulk
of the rows, stay unmarked.
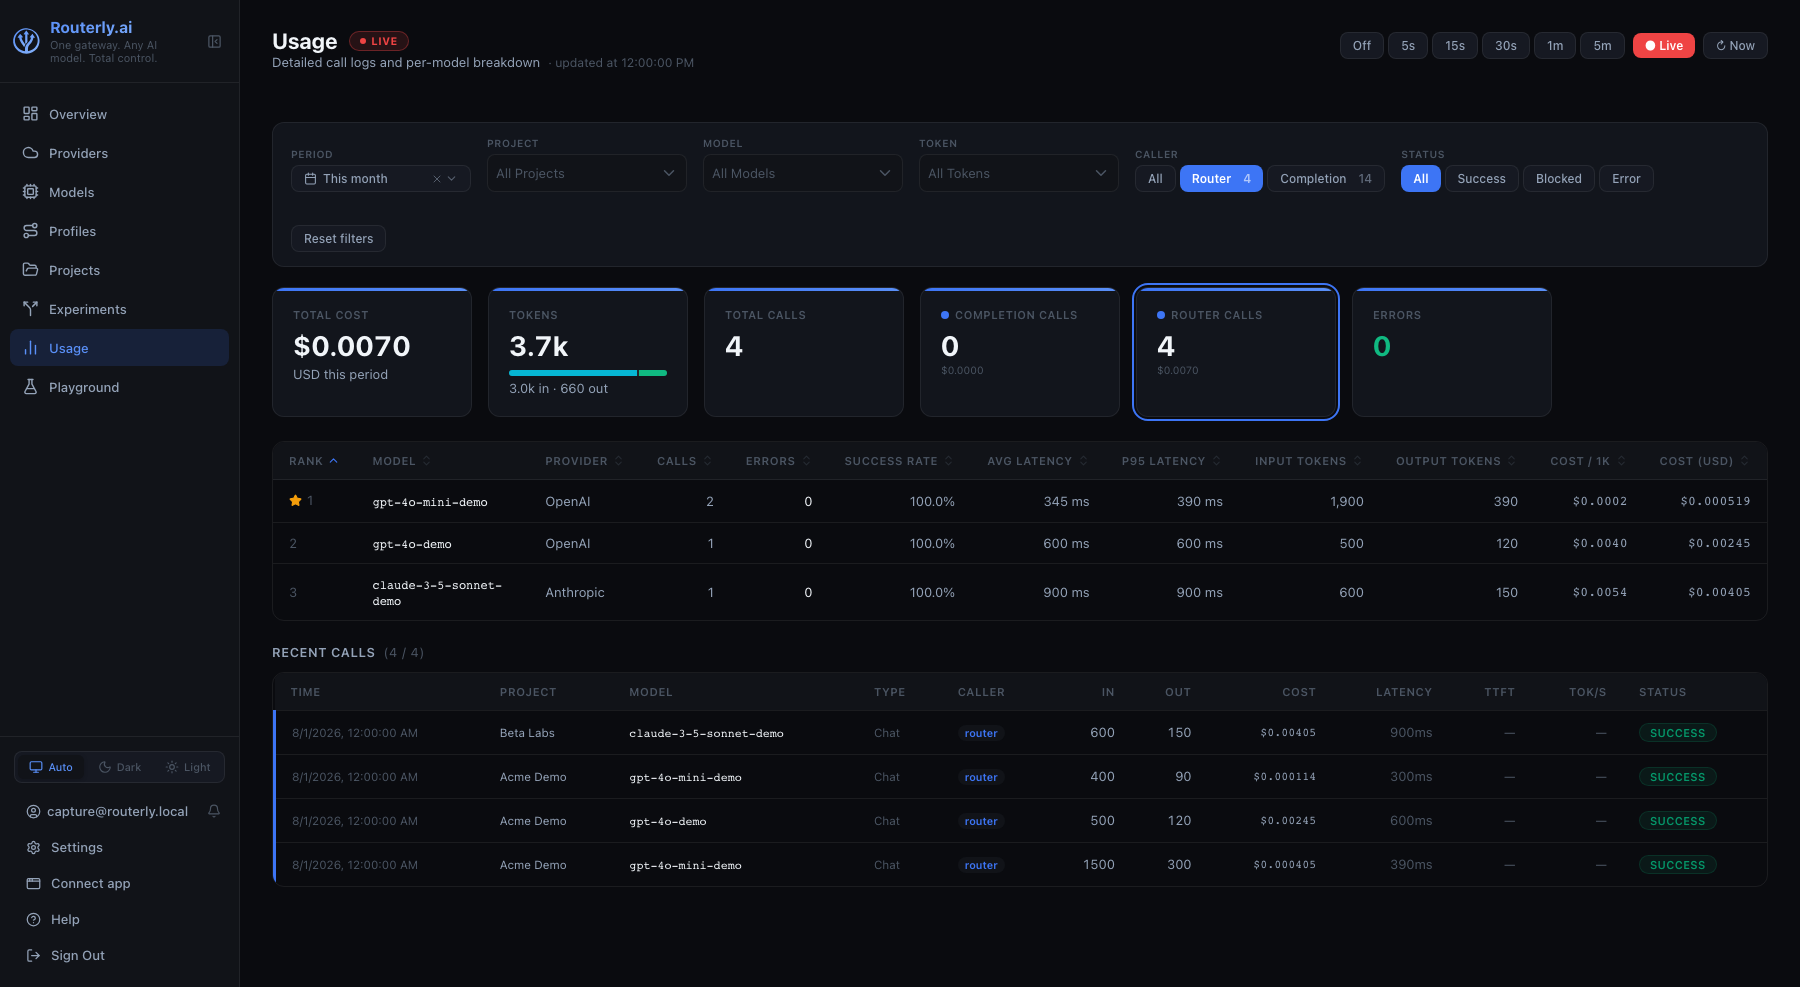
The Status badge in the table uses colour coding:
| Outcome | Badge colour |
|---|---|
success | Green |
blocked | Amber |
error / other | Red |
Click any row to open the full Trace view (/dashboard/usage/<record id>),
where the same token appears as its own Token field in the Identity card.
Trace View
The trace view reads on two levels: a summary card at the top of the page, and the trace log below it.
Summary
The card is built from the trace:recap entry the service writes when the
request finishes, so it never disagrees with the log below it. It carries:
| Part | Contents |
|---|---|
| Header | Outcome (ok, blocked, error, incomplete), model, provider, number of attempts when the router had to retry, total duration, total cost |
| Metrics | Input/output tokens, cached tokens when the provider reported any, latency, TTFT, throughput |
| Guardrails | Rules configured, triggered, skipped, injected, and the rule that blocked the request |
| PII | How many entities were redacted on the request and on the response |
| Optimizers | Steps run, applied, rolled back, and tokens saved |
| Router overhead | Calls the router itself made and what they cost -- kept out of the request's own numbers |
| Errors | One row per failed attempt: model and error |
A section only appears when that part of the pipeline did something.
Trace log
The log is the detail level: every entry the pipeline emitted, in the order the phases ran. It is deliberately dense -- open it when the summary says something went wrong and you need to see why. Entries are grouped by phase, the stage of the pipeline that produced them:
| Phase | What happened there |
|---|---|
| Ingress | The request arrived and was identified: router, token, session |
| Request · Preprocess | Everything that ran on the way in: PII scan and scrub, guardrail rules, optimizers |
| Routing · Prepare | The routing engine's input and its decision: active policies, scored candidates, selected model |
| Routing · Execute | The call to the provider: payload sent, response received, retries and fallbacks |
| Response · Postprocess | Everything that ran on the way out: response-side guardrails, PII scrub |
| Egress | What was written back to the client |
| Finalize | Cost and token accounting, and the export of the finished trace |
Each phase header carries the modules that spoke in it (pii, guardrail,
router, policy, model, cost), the number of events, and how long the
phase took. Click it to fold the phase away. Inside, every entry is stamped with
its offset from the start of the request (+83 ms), so a slow phase is visible
without reading the numbers.
A phase only appears when a module emitted something in it: a router with no guardrails and no PII scrubbing gets no Request · Preprocess section.
Older records carry no phase on their entries. Those fall back to the previous grouping -- Router Request, Router Response, Model Request, Model Response -- and are shown unchanged.
Every module on the path writes its own entries. The ones you meet most often:
| Trace entry | When |
|---|---|
guardrail:evaluated | After every guardrail check -- one row per configured rule, including the ones that only inject and the ones that were skipped, each with its type, target, score against threshold, duration and outcome |
guardrail:injected | A rule added text to the request -- lists the rules and how many characters they added |
guardrail:triggered | A request-side rule matched with log action (request continued) |
guardrail:response-triggered | A response-side rule matched with log action (response continued) |
pii:evaluated | After every PII scan, on the request and on the response -- active policies, entity types looked for, how many message contents were scanned, and per-entity redaction counts |
pii:scrubbed | PII was detected and replaced in the request or response |
optimizer:step | One row per optimizer step: tokens before and after, tokens saved, duration, and the reason when a step was skipped or rolled back |
budget:checked | The limit check before the upstream call -- the model, whether it was allowed, and every violated limit (metric, window, current, limit) |
egress:sent | What was written back to the client: kind, protocol, status, encoding, frames and bytes for a stream, or the error |
trace:recap | The end-of-request summary. It powers the card above and is not repeated in the log |
For a blocked request (judged rule that triggers), the trace includes the guardrail:evaluated entry and the block message (from the judge's reason field, or a built-in default if the judge fails). The block message is stored on the trace only and is not included in the wire response sent to the client.
The detail panel for each usage record shows:
| Field | Description |
|---|---|
| Guardrail Triggered | Identifier of the first rule that fired (e.g. regex:pattern, injection:dan-mode, topic:gpt-4o-mini) |
| Blocked By | Same as Guardrail Triggered -- present only when outcome is blocked |
| PII Redacted | Comma-separated list of entity types redacted (e.g. EMAIL, PHONE) |
| Session ID | Session identifier from the x-routerly-conversation-id header, if provided (useful for grouping multi-turn conversations or user sessions) |
| End user | End-user ID of the request, if provided |
| Tags | Custom metadata from the token that made the request (e.g., environment: production, team: backend); enables filtering and analysis by custom dimensions |
Live Polling
The page starts in Live mode, which refreshes every 2 seconds. A red pulsing badge appears next to the page title while Live is active.
To change the refresh interval, click any option in the interval selector directly. Doing so automatically exits Live mode and applies the selected interval:
| Interval | Meaning |
|---|---|
| Live | Refresh every 2 seconds (default on page load) |
| Off | Manual refresh only (click the refresh button) |
| 5 s | Refresh every 5 seconds |
| 15 s | Refresh every 15 seconds |
| 30 s | Refresh every 30 seconds |
| 1 min | Refresh every minute |
| 5 min | Refresh every 5 minutes |
The Period filter (date range picker) works independently of Live mode. You can change the displayed time window at any time, even while Live polling is active, without turning it off first.
Exporting Usage Data
Usage data is stored in ~/.routerly/data/usage.json as newline-delimited JSON. You can process it with any standard tool:
# Total cost this month
cat ~/.routerly/data/usage.json | \
  jq -r 'select(.timestamp | startswith("2025-07")) | .cost' | \
  awk '{sum+=$1} END {printf "Total: $%.4f\n", sum}'
For programmatic access, use the Usage API.